What Are Reasoning Models and When Should You Use Them?
Reasoning models aren't a strict upgrade — they're a dial for problems that reward it. Here's when to actually use one.
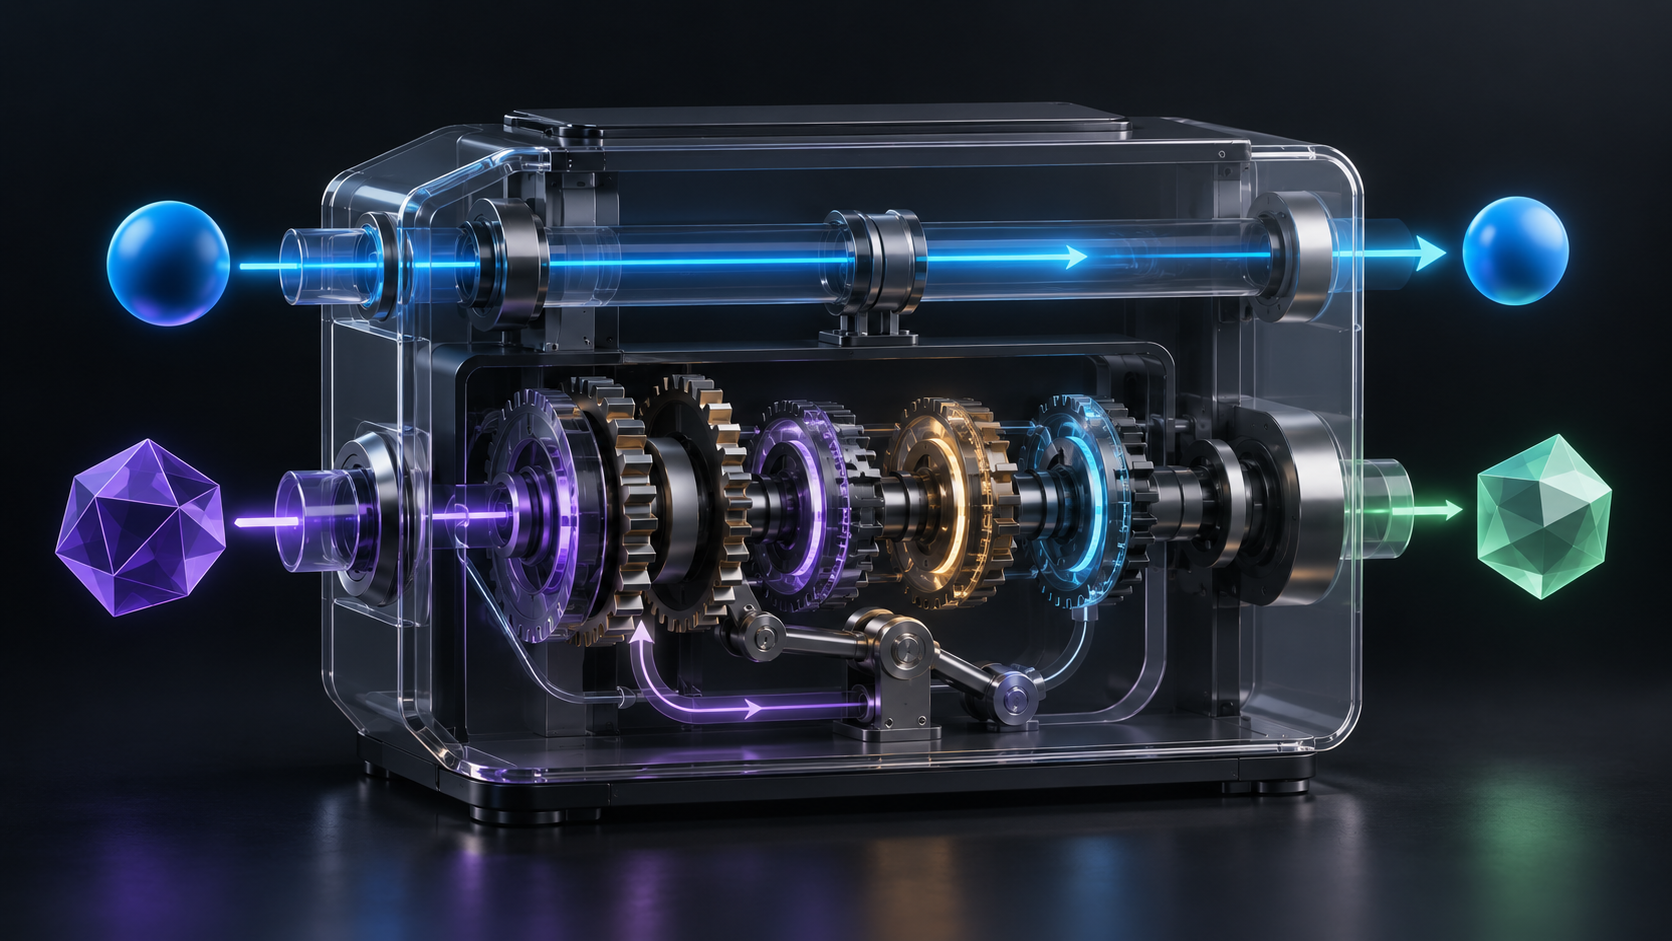
Since late 2024, a genuinely new category of AI model has moved from research curiosity to mainstream product feature: reasoning models, sometimes called large reasoning models, built specifically to think through a problem step by step before answering rather than generating a response in a single pass. Nearly every major lab now ships some version of this capability, and most current model families let you toggle it on or off, or dial the amount of reasoning up and down depending on the task. Understanding what that toggle actually does, and when it's worth using, has become a genuinely useful piece of practical knowledge for anyone working with AI regularly.
What actually makes a reasoning model different
A standard language model answers in one pass — it generates its response token by token, committing to a direction from the first word and continuing from there without a structured opportunity to step back and check its own work along the way. A reasoning model is trained differently. It's built to spend additional inference-time computation working through a problem before producing a final answer — planning, exploring different approaches, checking intermediate steps, and sometimes backtracking and revising earlier reasoning when a later step reveals a problem with it. That extra step-by-step process, often visible as a "thinking" trace before the final response, is what gives the category its name.
The training behind this is meaningfully different too. Where standard models are primarily optimized to generate fluent, broadly knowledgeable text, reasoning models are trained using reinforcement learning specifically aimed at rewarding correct multi-step problem solving, with the step-by-step reasoning process emerging as a learned behavior rather than something explicitly programmed in. That training difference is why reasoning models aren't simply "the same model thinking longer" — they're built with a different objective from the ground up, one that specifically rewards getting a multi-step answer right over sounding fluent along the way.
Where the gains actually show up
The performance difference between reasoning and standard models isn't evenly distributed across every kind of task, and understanding where the gap actually is matters more than knowing the gap exists at all. On tasks that require genuine multi-step logical inference — advanced mathematics, algorithmic code generation, rigorous scientific analysis — the difference is substantial and well documented. On graduate-level science benchmarks like GPQA Diamond, reasoning models have shown gains of fifteen to twenty-five percentage points over their non-reasoning counterparts, a gap large enough to represent a genuinely different tier of capability rather than a marginal improvement.
That gap collapses almost entirely, though, on a wide range of everyday tasks. Summarization, translation, straightforward content generation, simple classification, data extraction, and ordinary conversational response show a near-zero accuracy difference between reasoning and standard models. These are pattern-matching and generation tasks rather than genuine multi-step reasoning problems, and standard models are already operating at or near the ceiling of what's achievable on them — the extra deliberation a reasoning model applies isn't solving a problem that was actually there.
Why reasoning isn't a strict upgrade
The most important practical insight in how to think about reasoning models is that they aren't a better version of a standard model to be used by default whenever available — they're a different tool suited to a different category of problem, and treating reasoning as an automatic upgrade is a genuinely expensive mistake. Reasoning models spend meaningfully more tokens and more time producing an answer, since generating that internal step-by-step process before the final response is itself computationally costly. On a task that doesn't actually benefit from that deliberation, you're paying real latency and real cost for thinking the task never needed in the first place.
There's a sharper way to frame the decision that's become common among practitioners actually building with these models: reasoning is worth the added cost specifically when a task has multiple steps where an early wrong turn wrecks everything that follows — math, code that has to actually execute correctly, planning, constraint-heavy analysis — and you can genuinely afford the extra latency and cost that comes with it. For everything else — retrieval, summarization, classification, ordinary chat — a standard model's speed and lower cost win cleanly, because the accuracy you'd gain from reasoning is negligible on tasks that don't reward the extra deliberation to begin with.
A genuine limitation worth knowing about
It's also worth being aware of a more surprising finding that's emerged from recent research, because it complicates the simple "more reasoning is always better on hard problems" intuition. Research examining reasoning models across a range of problem difficulties has found that reasoning effort and accuracy don't scale together indefinitely — past a certain level of problem complexity, the accuracy of reasoning models has actually been observed to decline, even as the model continues to spend more computation reasoning about the problem. That's a meaningfully different picture than "reasoning models get better the harder the problem gets," and it's a useful check against over-trusting a reasoning model's output on the very hardest end of the difficulty spectrum, precisely where its extended deliberation might look most impressive and least warrant unquestioned trust.
There's a second, less intuitive caution worth naming too. Research specifically testing the assumption that reasoning models are inherently safer because they can "think through" a problem and catch issues has found that this isn't a reliable guarantee — in some adversarial testing, the additional reasoning capacity has been shown to enable more sophisticated failure modes rather than reliably preventing them, challenging the assumption that visible step-by-step thinking automatically makes a model's output more trustworthy. Reasoning helps with getting a multi-step problem right; it isn't automatically a safety or reliability guarantee on top of that.
How to actually decide, in practice
Put together, the practical decision framework is simpler than the underlying research might suggest. Ask whether the task genuinely has multiple dependent steps where an early mistake would compound into a wrong final answer — a complex debugging problem, a multi-step mathematical derivation, a piece of analysis that has to hold up under scrutiny where getting an early assumption wrong invalidates everything built on top of it. If yes, and the extra latency and cost are acceptable for the value of getting that specific answer right, reasoning is very likely worth it. If the task is closer to retrieval, summarization, straightforward drafting, or routine classification — the kind of work where a standard model already performs at or near ceiling — reasoning is unlikely to meaningfully improve the outcome and will reliably cost more time and money to get there. Reasoning is best treated as a dial to reach for deliberately on the specific problems that actually reward it, not a default setting to leave on for everything.
Where Kahlo fits into this
This is exactly the kind of decision Kahlo's smart router is built to make on your behalf, without requiring you to understand the underlying tradeoff in detail before you can get a good answer. Routine requests — summarization, drafting, quick lookups — get sent to fast, standard models by default, where reasoning wouldn't meaningfully improve the outcome and would only add cost and latency. Genuinely hard, multi-step requests get routed toward models with reasoning capability actually suited to that kind of deliberation, matching the tool to the task automatically rather than leaving reasoning on as a blanket default or off as a blanket restriction.
For the moments where a reasoning model's answer to a genuinely hard problem needs a second check — given the real, documented limits of reasoning models at the far end of problem difficulty — Council and Compare give you a way to bring more than one model's reasoning into the same answer, rather than trusting a single model's extended deliberation as automatically correct simply because it visibly thought longer to get there. That's the practical version of the lesson underneath all of this research: reasoning is a genuinely powerful tool for the problems that call for it, and a genuinely wasted one for the problems that don't, and the right answer depends on which kind of problem is actually in front of you.